The T-Rex Model is an open-vocabulary object detection system designed to find visual objects beyond a fixed label list. Traditional detectors often recognize categories such as cars, people, or dogs. T-Rex Model can accept a text description or a visual example instead. This makes it useful when a project needs to identify unusual products, tools, plant species, or workplace equipment.
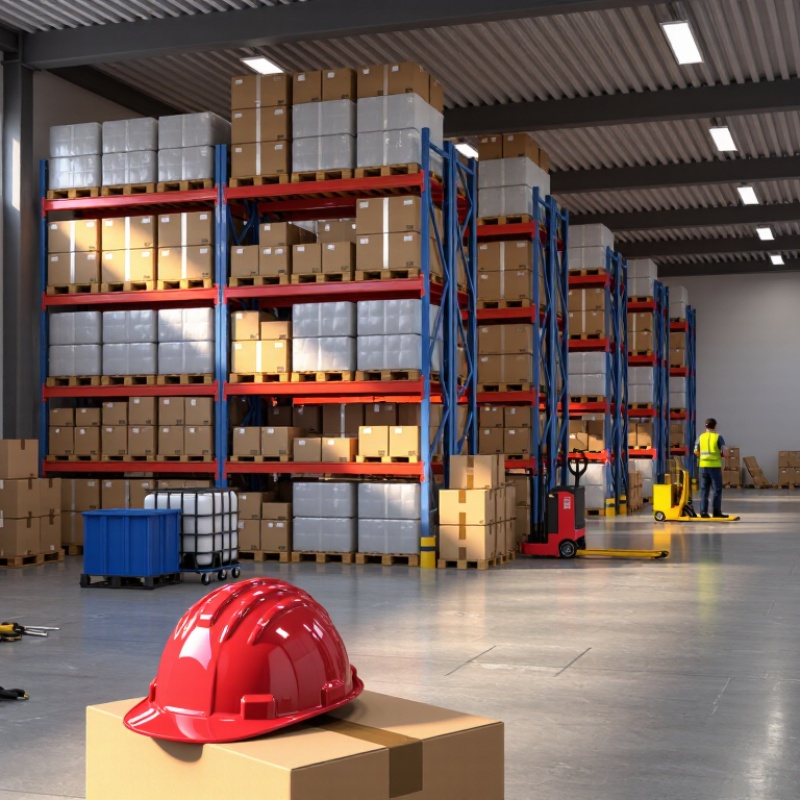
Its workflow is easier to understand through a simple image. Imagine uploading a warehouse photograph and entering “red safety helmet.” The model examines the image, compares visual regions with the requested concept, and returns likely bounding boxes. It may also provide confidence scores, helping users review uncertain results. In some versions, a reference image can guide detection when words do not describe the target clearly. The system typically combines image encoding, language or example matching, and region prediction.
The details matter.
This process is not magic. Lighting, shadows, blocked objects, poor image quality, and unfamiliar examples can reduce accuracy. A model may confuse a red cap with a helmet, especially in a crowded scene. Reliable use requires testing on representative images, checking false positives, and comparing results with human judgment. Published research and official technical documentation should guide serious deployment, rather than promotional claims alone. The T-Rex Model can simplify flexible detection, but it still needs careful prompts, measurable evaluation, and responsible oversight. That limitation is easy to overlook.
The T Rex Model usually refers to an artificial intelligence model designed to recognize objects in images or video. It can connect a visual target with a text description, such as “red helmet” or “wooden chair.” Unlike traditional systems, it may identify unfamiliar objects without requiring thousands of labeled examples for every category.
How does it work?
The model first converts an image into visual features. It also changes a written prompt into numerical features. Then, it compares both representations to locate matching areas, often drawing boxes around possible objects. In a warehouse image, for example, it might find a damaged package after receiving a suitable description. Results still depend on image quality, wording, lighting, and training data. That limitation matters. A confident prediction can still be wrong.
Tips:
Use short, specific descriptions. Mention color, shape, position, or visible condition. Test the model with clear images before trusting it in important workflows. Keep human review when mistakes could affect safety, privacy, or financial decisions. Logs can also reveal repeated errors, although many users forget this step. The name “T Rex Model” may describe different tools, so technical documentation should be checked before deployment. More testing is wise.
What Is the T Rex Model and How Does It Work?
The T Rex model is not one universally standardized system. The term usually describes an AI framework built to recognize patterns, rank information, and produce useful predictions. Its origins reflect a practical problem: organizations collect more data than human teams can review. Earlier systems followed fixed rules. Modern T Rex-style systems learn from examples, then adjust their outputs when new evidence appears.
A typical workflow has three stages. Data enters through text, images, numbers, or sensor records. The model converts these inputs into measurable features. It then compares relationships across the dataset before generating a prediction or recommendation. A review layer checks confidence, missing information, and unusual results. This matters because fluent output can still be wrong. I have found that unclear training data often creates more trouble than complex software.
Its purpose is controlled decision support, not blind automation. The 2025 AI Index Report records a sharp rise in model capability while noting persistent reliability gaps. A 2024 global enterprise survey found that 65% of organizations regularly used generative AI, showing strong adoption pressure. Yet adoption is not proof of accuracy. The T Rex model needs clean data, documented testing, and human review. It should also record why an output changed. Small details matter: a missing date, a biased sample, or one damaged sensor can distort the result. The framework remains useful, but its assumptions deserve regular challenge.
The T Rex model is a modular machine-learning system designed to turn input data into structured predictions. Its name can describe different architectures, so technical documentation matters. A reliable implementation usually has four core components: the data layer, feature encoder, prediction head, and evaluation pipeline.
The data layer cleans text, images, or sensor records before processing. Poor inputs create confident errors. The encoder converts raw information into numerical representations. These vectors help the model detect patterns, relationships, and context.
The prediction head then produces a label, score, or generated response. During training, a loss function compares predictions with verified examples. Optimizers adjust the model’s internal weights.
Evaluation should include accuracy, calibration, latency, and failure cases. The Stanford AI Index 2024 reported a 280-fold reduction in inference costs for GPT-3.5-level systems between November 2022 and October 2023. Lower costs make repeated testing more practical, but they do not guarantee better decisions.
IDC forecasts worldwide artificial intelligence spending will reach $632 billion by 2028, showing why transparent model design matters.
Tips:
Keep each component measurable. Record data sources, version changes, and error patterns. Test unusual inputs, not only clean examples.
A useful improvement is adding human review for high-impact outputs. This can slow deployment. It can also expose weaknesses that automated scores miss.
The model should remain understandable enough to challenge. That part is often neglected.
What Is the T Rex Model and How Does It Work?
The T Rex model is a machine learning framework designed to study patterns and produce predictions. Its exact structure may differ across technical fields. In practice, it usually processes large datasets through several connected stages.
The process begins with data collection. Information may include text, images, measurements, or user activity. The system then removes duplicates, fills missing values, and converts raw details into a consistent format. Small errors matter here. Poor input can weaken every later result.
Next, the model identifies meaningful features. It may notice repeated words, sharp image edges, or unusual numerical changes. During training, it compares predictions with known answers. An error score shows where the model performed poorly. The system adjusts internal weights and repeats this cycle many times. It is a gradual process.
After training, new data enters the model. The same preparation steps are applied before prediction. The model evaluates learned patterns and assigns an output, such as a category, score, or estimated value. Human reviewers should test these results against fresh data. I would not treat one accurate prediction as proof of reliability. Bias, incomplete records, and changing conditions can still distort performance. Monitoring remains necessary after deployment, especially when the model influences important decisions.
| Step | Model Stage | Data or Input Used | How the Model Works | Typical Output | Main Uncertainty |
|---|---|---|---|---|---|
| 1 | Fossil evidence collection | Bones, teeth, preserved footprints, skin impressions, and the geological layer in which fossils are found. | Researchers document specimen measurements, identify damaged or missing areas, and compare individual fossils with other tyrannosaurid material. | A cleaned anatomical dataset for reconstruction. | Incomplete skeletons and distortion caused by fossilization. |
| 2 | Anatomical reconstruction | Articulated bone positions, joint surfaces, muscle attachment areas, and comparisons with living birds and reptiles. | The skeleton is digitally or physically assembled. Joint limits and muscle paths are estimated from anatomy and comparative biology. | A three-dimensional skeletal and soft-tissue framework. | Soft tissues, posture, and muscle size are not preserved directly. |
| 3 | Body-size estimation | Femur length, body length, body volume, and scaling relationships from well-preserved specimens. | Length and mass are calculated using more than one method, such as volumetric reconstruction and equations based on limb-bone dimensions. | Large adults are generally estimated at about 12 metres long, with mass estimates commonly ranging from roughly 5 to 9 metric tonnes. | Mass changes substantially with body shape, fat level, and the specimen selected. |
| 4 | Movement analysis | Leg proportions, joint geometry, estimated muscle forces, and biomechanical limits. | Computer simulations test walking and running scenarios while checking whether estimated forces remain mechanically plausible. | A range of possible walking speeds and movement patterns rather than one confirmed speed. | Speed depends on muscle assumptions, posture, balance, and whether the animal was walking or running. |
| 5 | Bite-force modelling | Skull dimensions, tooth position, jaw-muscle attachment areas, and mechanical leverage. | The model estimates jaw torque and force at different tooth positions. Front and rear teeth can produce different force values. | Adult estimates are often in the tens of thousands of newtons, with published values varying by method and location in the jaw. | Muscle reconstruction and tooth-contact assumptions strongly affect the result. |
| 6 | Feeding and stress testing | Tooth shape, jaw movement, skull strength, bone structure, and bite-force outputs. | The reconstruction tests how the skull and teeth respond to different loads, including pulling and biting stresses. | Possible feeding behaviours, tooth-loading patterns, and areas vulnerable to high stress. | Behaviour cannot be observed directly and must be inferred from anatomy and damage patterns. |
| 7 | Environmental context | Rock type, fossil location, associated plants and animals, climate indicators, and estimated age of the deposit. | The physical reconstruction is combined with habitat evidence to evaluate likely food availability, climate, and ecological relationships. | A more complete interpretation of habitat and possible ecological role. | Ancient ecosystems are represented by incomplete fossil samples. |
| 8 | Validation and revision | New fossil discoveries, revised measurements, alternative body shapes, and independent biomechanical studies. | Researchers compare model predictions with preserved evidence and rerun the model when new data or improved methods become available. | A range of evidence-based results with confidence levels instead of a single definitive answer. | Scientific reconstructions remain provisional and may change as evidence improves. |
Note: Measurements and performance estimates are scientific approximations. Results vary according to the fossil specimen, reconstruction method, and assumptions used in the model.
The T Rex model is a data-driven system for identifying patterns and producing predictions. Its name can describe different technical designs, so its exact structure depends on the field. In most applications, the model receives historical data, converts it into measurable features, and assigns scores to possible outcomes. It then compares those outcomes with known results and adjusts its internal parameters.
Its applications are practical.
Analysts may use it to detect unusual transactions, estimate equipment failures, classify documents, or forecast demand. A maintenance team, for example, could monitor vibration readings from a machine. A sudden change in the score might signal a problem before visible damage appears. The model can also support medical research, environmental monitoring, and supply planning. It works best when the data is relevant, recent, and carefully checked.
But its limitations matter.
Garbage in, garbage out.
Biased records can produce biased predictions. The model may also confuse correlation with causation, especially when several factors change together. Complex outputs can be difficult to explain to nontechnical users. Performance may decline when real-world conditions shift. This is called model drift. Human review remains necessary for high-impact decisions.
In practical testing, a strong score is not proof of truth. That weakness deserves attention. A T Rex model can assist expert judgment, but it should not quietly replace it.
It identifies visual objects or patterns in data. For images, it can connect a text description with a visible target. It may locate a damaged package or a wooden chair.
The model converts an image into visual features. It also converts written prompts into numerical features. Then, it compares both representations and may draw boxes around matching objects.
Use short, specific descriptions. Mention color, shape, position, and visible condition. A prompt like “small red box near the door” gives clearer guidance.
It may identify objects without thousands of labeled examples for every category. However, unfamiliar shapes and poor wording can confuse it. More testing is wise.
It can flag unusual transactions, estimate equipment failures, classify documents, or forecast demand. A maintenance team might watch machine vibrations. A sudden score change could suggest hidden damage.
It works best with relevant, recent, and carefully checked data. Poor records can create poor predictions. Garbage in, garbage out.
Lighting, image quality, wording, and changing conditions can reduce performance. Biased records may produce biased predictions. Model drift can appear when real-world patterns change.
No score proves truth. A confident prediction can still be wrong. Human review should remain for safety, privacy, medical, or financial decisions.
Keep logs of predictions, errors, and changing conditions. Review repeated mistakes with clear examples. People often forget this step, including careful teams.
The T-Rex Model is a structured framework designed to explain how a complex system can be understood, organized, and applied in practice. Its origins come from the need to simplify complicated processes by dividing them into clear stages and connected components. Rather than focusing on one narrow function, the model provides a broad view of how goals, inputs, operations, feedback, and results interact. Its main components help users identify what a system needs, how it processes information or resources, and how its performance can be evaluated.
The T-Rex Model works step by step: first, users define the objective; next, they collect and organize relevant inputs; then, they apply the model’s operating principles to produce a result. Finally, they review the outcome, identify weaknesses, and make improvements through feedback. This approach can support planning, education, research, problem-solving, and system evaluation. However, the model is not a universal solution. Its effectiveness depends on accurate information, suitable assumptions, and careful interpretation, while overly complex or changing situations may require additional methods.